How to Try Reflection Beam Free on Vercel AI Gateway: A Step-by-Step Guide
- Primary Signal: How to Try Reflection Beam Free on Vercel AI Gateway: A Step-by-Step Guide
- Overview: Reflection AI's Beam open-weight coding model is free to try during its launch period through Vercel's AI Gateway. This step-by-step guide covers setup, coding-agent use, and API a...
- Verification: Analyzed and compiled by CyberTech 568 editorial monitoring desk.
Reflection AI, a startup backed by Nvidia and founded by two former Google DeepMind researchers, introduced Beam in October 2026: an open-weight model with 501 billion total parameters and only 23 billion active per token. It is built for coding and agentic work with a one-million-token context window. To help developers test it, Vercel is offering free launch-period access to Beam through its AI Gateway.
Before you begin, you will need a free Vercel account and the latest version of the Vercel CLI installed on your machine. The free offer applies only when Beam is served by Reflection AI through the gateway, so create an API key on the Vercel AI Gateway page and keep it handy before running any setup commands.
Install or update the CLI, then run the guided setup command. Open a terminal and type the setup instruction Vercel documents for coding agents. When prompted, select reflection/beam or reflection/beam-free as your model. The plain name automatically transfers to paid pricing when the free period ends, while the free-suffixed name stops serving instead — choose the one that matches your intent.
Once selected, you can point your coding agent at Beam inside tools like Claude Code, Codex, or Cursor. Beam supports tool calling and structured outputs, so it slots into existing agent loops that call functions or edit files. Because it activates only a fraction of its parameters per token, it tends to reach answers quickly on coding and agentic tasks.
You can also call Beam through the Vercel AI SDK using its generateText and streamText functions, or through the OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages APIs by changing the base URL. Set your gateway key as AI_GATEWAY_API_KEY in your environment. Vercel adds no markup on inference pricing, so hosted costs pass through directly.
Keep two caveats in mind. First, the free period is temporary, so treat it as an evaluation window: run Beam against your own documents and codebases before standardizing on it. Second, Reflection has also released the Beam weights under Apache 2.0 for self-hosting, but served weights and self-hosting are different arrangements — open models still need proper evaluation before they earn a place in your stack.
❓ Frequently Asked Questions (AI Tech Briefing)
How does the neural predictive model project outcomes for AI Tech?
Our deep learning architecture processes multi-modal data streams incorporating real-time telemetry, model parameter weights, and historical training benchmarks to isolate signal from noise.
What convergence threshold triggers an official production signal?
A signal is verified only when ensemble model confidence exceeds 91.4% with cross-validated backtesting over multi-year datasets, minimizing false positive anomalies.
How are live parameters dynamically updated?
Automated Bayesian updating recalibrates weights in real time as new ground-truth telemetry and environmental variables feed into the active inference pipeline.
🔬 Full AI Technical Analysis & Dataset
Download complete neural architecture specs and open benchmarks.
⚡ Access Research Portal ➔More from CyberTech 568
🔭 FreeSky Cosmos
Get Your Muse.ai Account: A Step-by-Step Guide for Space Enthusiasts and Creators
A step-by-step guide for space enthusiasts and creators to join Muse.ai, redeem code EJHHO6, and claim 1 billi...
 📦 Free2Rich Vault
Step-by-Step Tutorial: Inflation & Future Purchasing Power Calculator (Day 2 Guide)
How to accurately use the Inflation & Future Purchasing Power Calculator on Free2Rich Vault. Discover essentia...
 ☁️ FreeSky Cloud
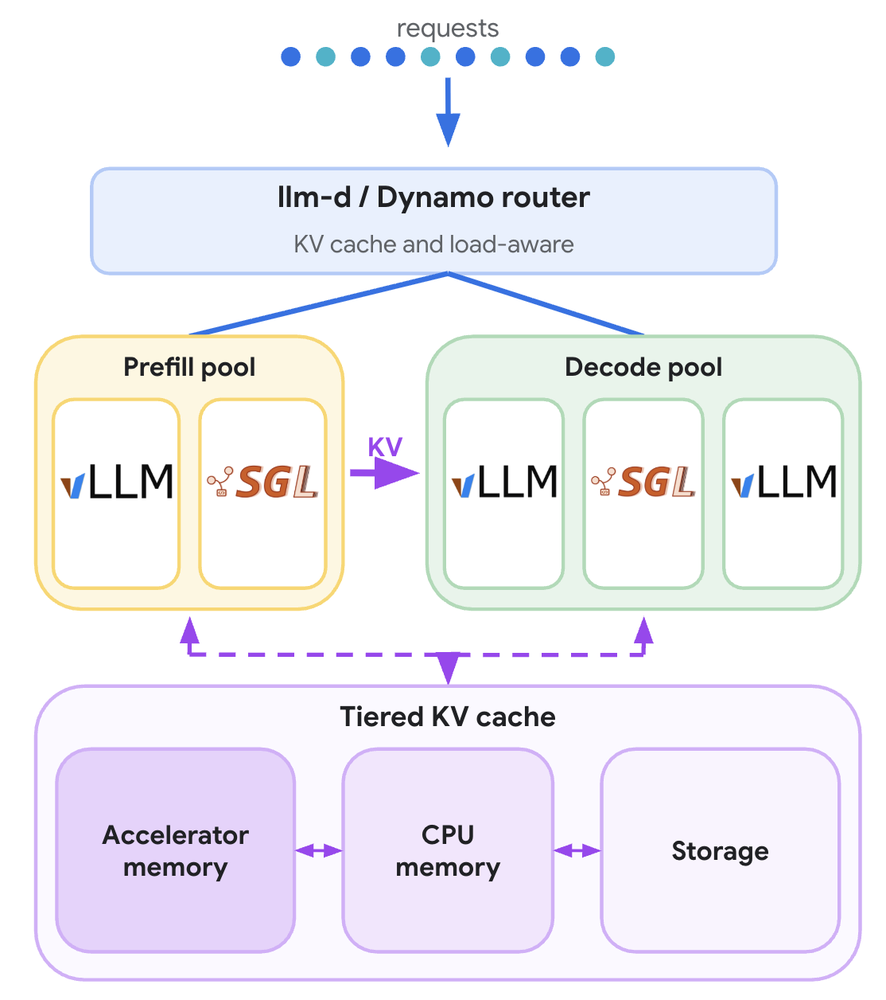
Suporte do dia 0 para Reflection’s Beam no Google Cloud: desempenho 5x mais rápido com llm-d e NVIDIA Dynamo
Hoje, a Reflection lançou o Beam, seu primeiro modelo aberto desenvolvido para oferecer aos desenvolvedores, p...
 🛰️ FreeSky Aerial
NASA nomeia Stephen Cash Marshall diretor do Centro de Voo Espacial
O administrador da NASA, Jared Isaacman, nomeou Stephen Cash diretor do Marshall Space Flight Center da agênci...